How We Moved Blog Image Uploads from Manual Server Work to the Admin UI and CDN
TekeraLab already had a CDN. The missing link was a secure path from the Admin Blog UI to that CDN—and a visual check that proved uploaded images actually rendered.
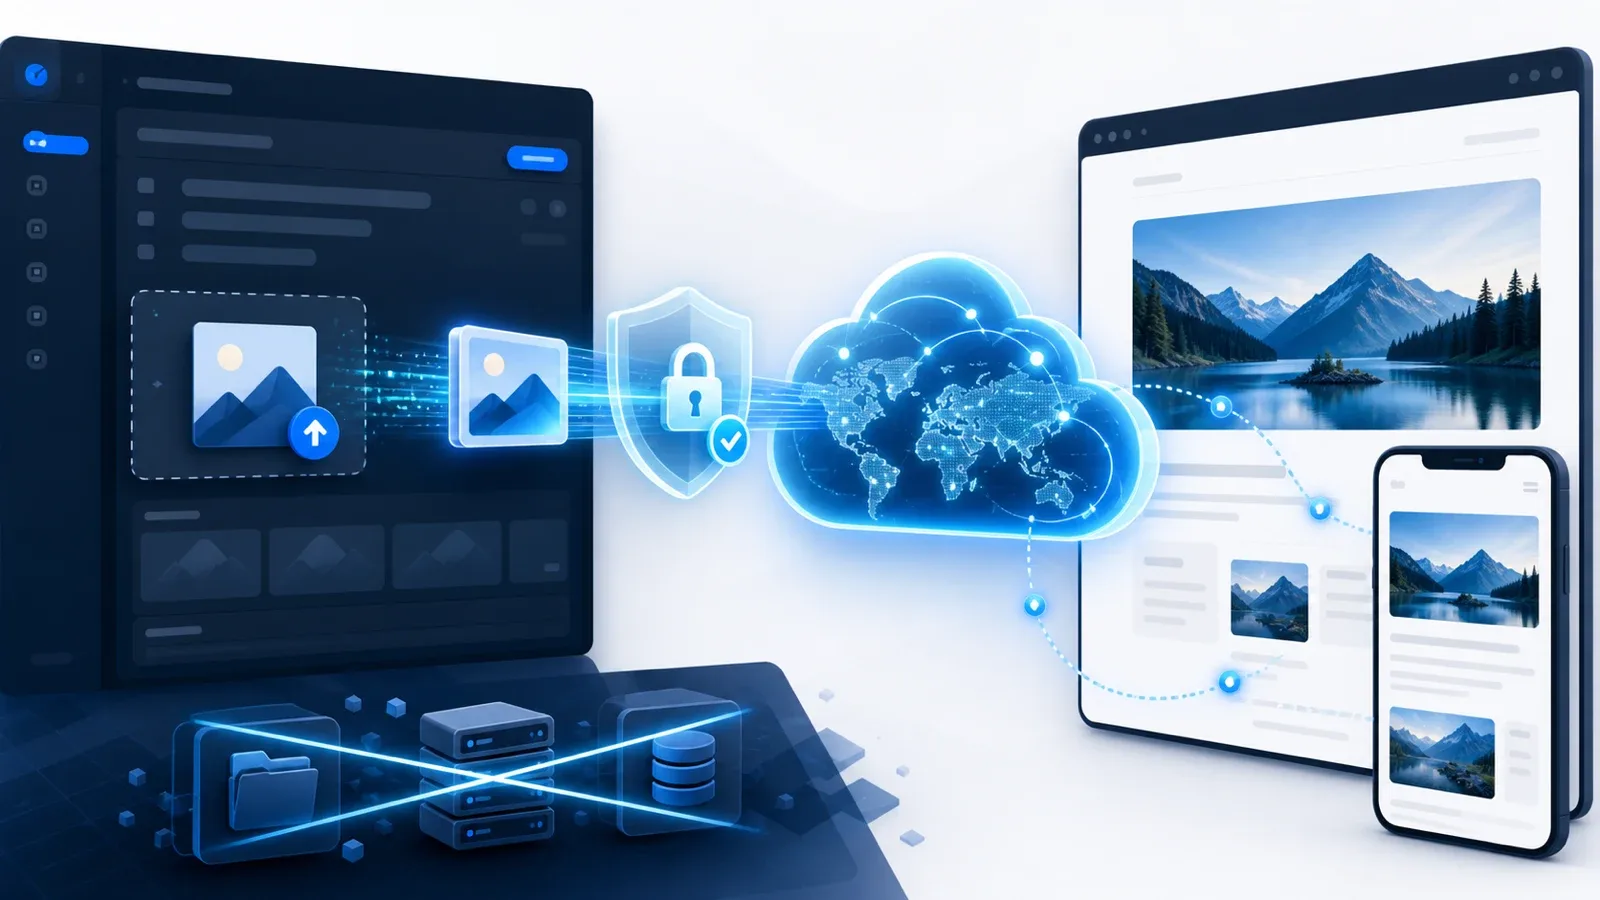
Publishing one article should not require a fresh code deployment or direct access to a server. Text, SEO fields, and images belong in the same editorial workflow—especially when a team intends to publish every day.
TekeraLab already had a working CDN. The missing part was the final connection between that permanent media layer and the authenticated Admin Blog interface.
The problem was not the absence of a CDN
A CDN can deliver files quickly and reliably, but it does not automatically give an editor a safe way to place those files there. Before the Admin workflow was completed, an image could still require someone with technical access to move it, find the public URL, and paste that address into the right field.
That may be manageable for an occasional article. At daily publishing volume, it becomes a bottleneck and gives infrastructure work to people who should be editing content.
The missing link between Admin and the existing CDN
The right solution was not another storage system. It was an authenticated upload path to the CDN we already operated. An authorized editor should be able to choose an image, specify how it will be used, upload it, and receive a stable public URL without leaving the article editor.
Cover, Open Graph, and body images can then be managed beside the title, article body, translations, and SEO metadata. A new article no longer needs code changes simply to make a picture public.
A secure upload is more than a button
The visible Upload button is only the front of the workflow. The important controls happen behind it: the endpoint must require an authenticated administrator and inspect the actual content of the file rather than trusting its filename.
File type, size, and destination need clear limits. A successful request should return one stable public URL, while a failed request should explain the problem without creating a half-finished media record. The goal is not accepting every file; it is providing one predictable gate for valid blog images.
The issue that only appeared when we looked at the real page
The API could accept a file and the CDN could return HTTP 200, yet the first real preview still exposed a problem: one URL form did not render correctly through the page’s image optimization path. Two technical components were healthy, but the reading experience was broken.
That is why visual verification matters. Upload success and a reachable file are necessary, but not sufficient. The image must appear inside the article on desktop and mobile, with its intended dimensions and alternative text, and without a broken frame.
What changed for everyday publishing
The desired path is now simple: the editor selects an image in Admin Blog, the file passes the permitted checks, the existing CDN returns a public address, and that address becomes the Cover, OG, or body image. The content team no longer needs extra server access.
This change also clarifies responsibility. Infrastructure maintains a safe and durable path; editors prepare and verify the article from the interface; and both groups can inspect the same public result. It is one of the practical foundations behind our four-language publishing workflow.
The missing piece was not a new CDN—it was the last metre of the publishing path. Connecting Admin Blog to the CDN turned image handling from manual server work into a normal editorial action. The most important lesson remained visual: a green API is not the end of the test; the reader must be able to see the image on the page.
Performance is part of publishing
A secure Admin-to-CDN path solved manual image handling, but publishing quality also depends on what the browser actually receives. We measured delivered file sizes and response times instead of relying on a compression setting alone. The result was a lighter, faster Admin experience and a clearer rule: configuration names are not evidence; delivered output is.
Mobile is where small details grow
On a narrow screen, weak heading hierarchy, misplaced navigation, and unnecessary empty space make an article tiring to read. We reviewed the real blog article, index, category, and search pages at mobile size so the visual language would remain consistent from discovery to reading.
One workflow, one definition of Done
The final publishing check now joins four things: the page loads quickly, the article is comfortable to read, the CDN image remains public and visible, and the real desktop and mobile pages are inspected. An upload response or a green API is necessary, but the reader’s screen is the final proof.
Ask a question
Got a question about this post? Drop your email and we’ll reply.
Get notified of new posts
1–2 emails a month on social media, AI and running a small business. No spam.
Related posts
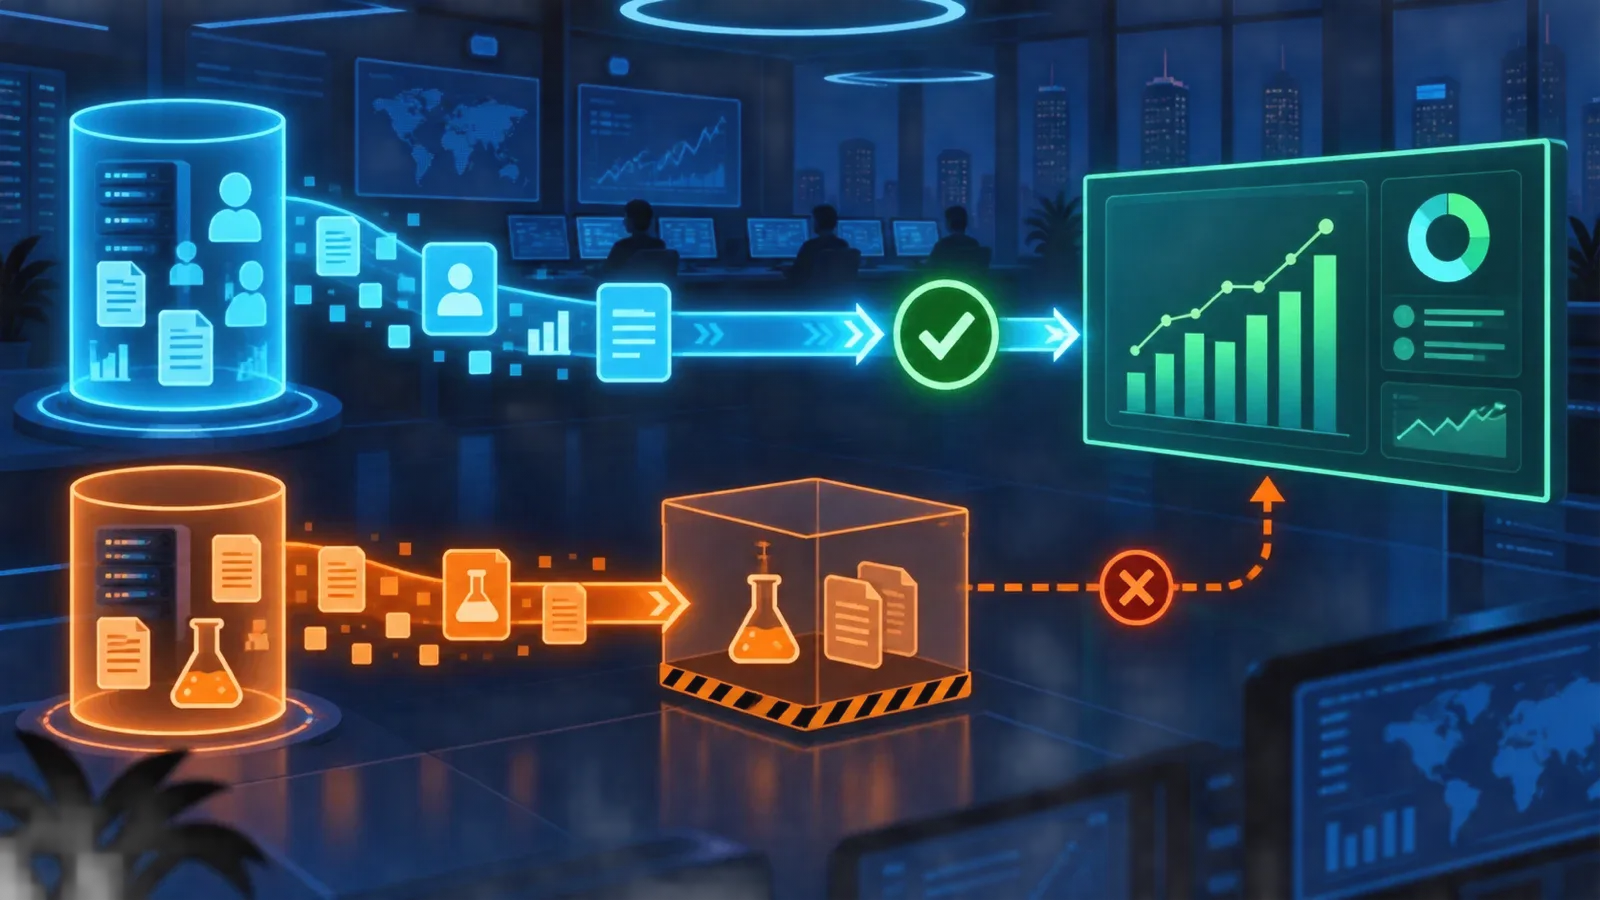
Don’t Delete Test Data—Separate It from Real Revenue
Hiding test data makes defects invisible; counting it in KPIs corrupts decisions. The solution is to separate visibility from revenue recognition.
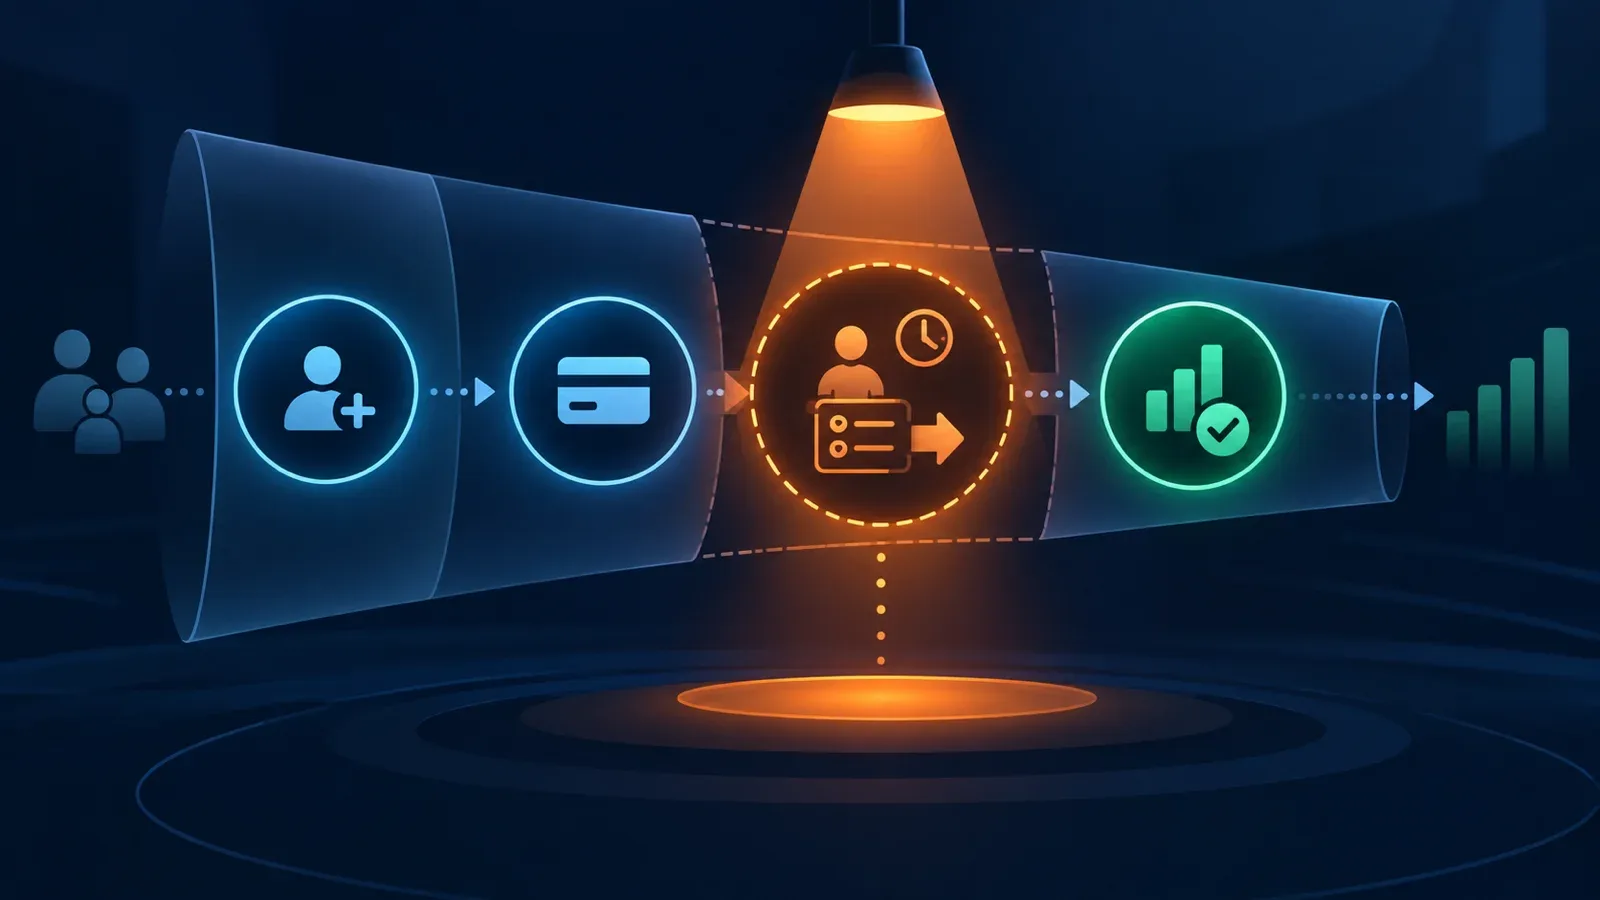
The Invisible Revenue Funnel Stage: Where Payments Disappear
Between payment intent and recognized revenue, customers can disappear into untracked states. Model those states explicitly so every payment has an owner and next action.
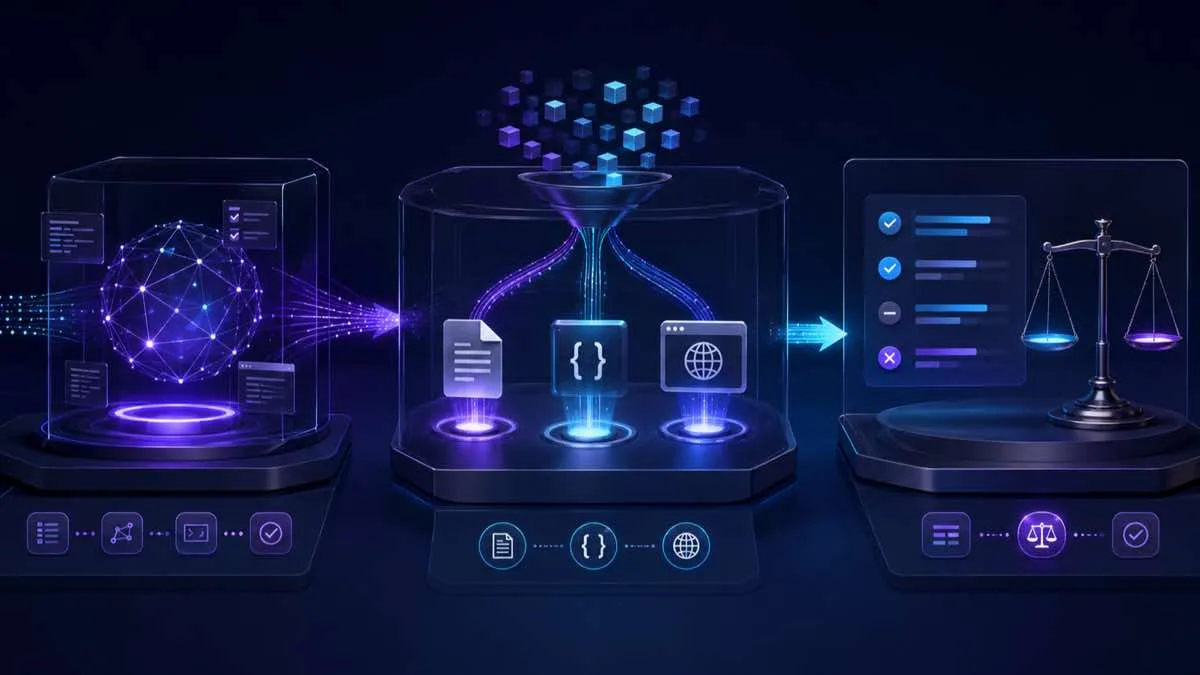
When an AI Agent Checks Its Own Evidence: How to Build Truly Independent Evaluation
When an evaluator trusts an agent's own report, it may validate the claim instead of the result. This guide separates execution, evidence collection, and evaluation.